Search results for tag #refactoring

Stop asking AI to “clean this up”: a safe refactoring loop (with 2 free prompts)
Josh Marino 🦞 (@AIRoboticsInt)
Gemini 4 Argon의 최대 출력 길이가 기존 64K에서 100만 토큰으로 확대됐다는 내용이다. 멀티파일 애플리케이션 생성이나 대규모 리팩터링을 한 번의 응답으로 처리할 수 있는 규모이며, 얼리 액세스 사용자는 긴 작업에서 중도 포기가 적었다고 평가했다. 다만 3D 작업 성능 평가는 유보해야 한다고 언급했다.

Over time, some couples drift apart. They still share a sofa, but they’re really just cohabiting 💔.
What’s true for couples is also true for our shared abstractions.
Here’s how to spot the cohabiting trap, and escape it: https://williamboles.com/escaping-the-cohabiting-trap/
A late cleanup request arrived with a four-hundred-line diff that rewrote validation, deduplication, and persistence in one pass. The existing tests covered only the happy path, so a green CI run could not explain the legacy rows. The reviewer needed a smaller change that preserved every observed output before any structural boundary was allowed to move. This composite scenario shows how to freeze those outputs, then accept only the smallest safe edit.
The module under review is a batch upload normalizer that grew by successive tickets rather than by design. It reads a list of records, fills missing defaults, drops exact repeats, and writes survivors to storage. Those four jobs share one function, so a cleanup that touches all of them cannot be reviewed as one claim. The method below separates observation from edit, and it does not depend on any particular assistant.
Name the behavior you will freeze
Before changing code, write down the inputs that already matter and the outputs you are willing to treat as current truth. Include awkward rows from production samples, not only the tidy examples attached to the latest ticket. A characterization file is a pinned record of those pairs, not a statement that the behavior is desirable. If a row is known to be wrong, mark it as accepted debt instead of silently correcting it during the same change.
Three observations keep the freeze honest when the repository is already messy.
- Record the returned list and the store payload, because a matching return can still hide a second write.
- Preserve the original row order, because a sort that looks cleaner can change which duplicate survives.
- Keep skipped rows visible in the fixture notes, because a deleted branch is still a behavior change.
That list is the review contract for this module, and it should stay visible in the pull request description. It is narrower than a repository-wide characterization suite, and it is not a license to rewrite neighboring helpers. This pass does not hash a repository-wide side-effect ledger, and it does not ask you to freeze every neighboring seam. The next section turns the contract into a local command you can rerun after every proposed diff.
Pin a fixture before the extraction
The following Python example is a proposed harness, not a log from a measured production run. It uses a memory store so the test process does not touch a real database or a shared queue. The cases cover a blank SKU, a negative quantity, an exact repeat, and a lowercase SKU that the current code uppercases. Run the capture against the untouched function, then commit the fixture before you accept any cleanup.
import json
from pathlib import Path
class MemoryStore:
def __init__(self):
self.batches =
[] def write(self, rows):
self.batches.append([dict(row) for row in rows])
def normalize_upload_batch(records, store):
seen = set()
kept =
[] for record in records:
sku = (record.get('sku') or '').strip().upper()
qty = record.get('qty', 0) or 0
if not sku or qty < 0:
continue
key = (sku, int(qty))
if key in seen:
continue
seen.add(key)
kept.append({'sku': sku, 'qty': int(qty)})
store.write(kept)
return kept
CASES = [
{
'name': 'blank-sku',
'records': [{'sku': ' ', 'qty': 2}],
'debt': False,
},
{
'name': 'negative-qty',
'records': [{'sku': 'ab1', 'qty': -1}],
'debt': False,
},
{
'name': 'case-and-repeat',
'records': [
{'sku': 'ab1', 'qty': 2},
{'sku': ' AB1 ', 'qty': 2},
{'sku': 'ab1', 'qty': 3},
],
'debt': False,
},
]
def capture(cases):
report =
[] for case in cases:
store = MemoryStore()
returned = normalize_upload_batch(case['records'], store)
report.append({
'name': case['name'],
'debt': case['debt'],
'returned': returned,
'written': store.batches,
})
return report
def main():
path = Path('batch_characterization.json')
payload = json.dumps(capture(CASES), indent=2) + '\n'
path.write_text(payload, encoding='utf-8')
print('wrote', path)
if __name__ == '__main__':
main()
Compare the fixture, do not skim the diff
A second, ordinary command compares a fresh capture with the fixture you already committed to the branch. The comparison is a textual check of the JSON, not a visual skim of a large assistant diff. If you later correct a debt row, change the fixture in a separate commit and state the product reason in that commit message. Until you trust the harness, treat a non-empty fixture diff as a failed review rather than as a suggestion.
Save the harness as capture_batch.py beside the fixture so the commands below match the file you run.
python capture_batch.py
git diff -- batch_characterization.json
The sample function above is embedded so a reader can follow the article without cloning a repository. In a real repository, import the existing function instead of pasting a simplified copy into the test file. A pasted copy can drift from the production function and then bless the wrong behavior during review. Keep the fixture next to the module so a reviewer can open both without searching the whole tree.
Score the smallest safe change
After the fixture is committed, the only edit this pass allows is an extraction of the pure selection loop. The wrapper may call the new function and then perform exactly one write to the existing store. It may not add a sort, a new skip rule, a retry, or a second store call. The table below is the acceptance gate for the diff, and a single failed row is enough to reject the change.
Check
Accept this pass
Send it back
Files touched
The one module that owns the batch function
Any helper outside that file
Fixture JSON
Unchanged after a local rerun
Any added, dropped, or reordered field
Store writes
One write, matching the returned rows
An extra write, a cleared batch, or a write before selection
New branches
None
A fallback, a retry, or a temporary compatibility flag
Debt rows
Still marked debt in the fixture
Quietly corrected inside the cleanup
The extraction that the gate allows
The extracted shape that satisfies every row of the table looks like the unexecuted sketch below. It remains a proposal until you rerun the capture and the fixture diff is completely empty. Notice that the skip rules are copied, not improved, because an improvement is a behavior change and belongs in a later commit. The wrapper stays responsible for the write, so persistence bugs are not mixed into the pure move.
def select_upload_rows(records):
seen = set()
kept =
[] for record in records:
sku = (record.get('sku') or '').strip().upper()
qty = record.get('qty', 0) or 0
if not sku or qty < 0:
continue
key = (sku, int(qty))
if key in seen:
continue
seen.add(key)
kept.append({'sku': sku, 'qty': int(qty)})
return kept
def normalize_upload_batch(records, store):
kept = select_upload_rows(records)
store.write(kept)
return kept
Follow the same four steps
- Commit the characterization fixture that you generated from the untouched function before any extraction work begins.
- Extract only the selection loop into a pure helper, and leave the storage write inside the original wrapper.
- Rerun the local capture after that extraction and require an empty diff on the committed fixture file.
- Schedule debt corrections, retries, and storage changes as later commits that carry their own expected results.
That order matters more than the size or brand of the assistant that happened to propose the cleanup. A small extraction can still be wrong if you regenerate the fixture after the edit and then treat the new file as the baseline. Commit the baseline first, or the acceptance gate has nothing stable left to protect later. If step three fails, restore the extraction and inspect the case, rather than widening the diff to force a match.
Let an assistant draft, then keep the gate local
Disclosure: This article was prepared as part of MonkeyCode's product outreach.
A coding assistant can draft fixture cases or the extraction sketch after you have already named the rows you care about. For this draft, the operator supplied two availability claims: free model access and a free server option. This article does not state model names, token quotas, hardware size, duration, or benchmark scores, because those details were not provided as primary sources. Check the project documentation on the day you start, because availability terms can change and should not be copied from an older post.
The useful split should stay small even when the assistant is allowed to see the whole repository. Ask it to propose cases that match the contract, then paste those cases into the harness and run the capture yourself. Ask for the extraction only after the fixture is committed, and reject any diff that fails a row in the table. A free server can be a convenient place to run that capture when your laptop cannot match the language version. The committed fixture still belongs in the repository you review, not only on the temporary machine.
If that gate matches how you already review cleanups, read the current access notes before you try it. Then run the same fixture workflow on one module you can execute on a machine you control. Keep the product optional: the harness, the table, and the empty fixture diff are the parts a teammate can reuse without an account. A reviewer should never treat a model-written explanation as proof that the fixture file remained stable.
Limitations and who should skip this
This approach freezes current behavior, including bugs that nobody has yet scheduled for a product fix. It is a poor fit when the ticket requires a visible behavior change inside the same pull request. It is also a poor fit when you cannot obtain representative rows, because an empty fixture will bless whatever the first draft happens to emit. A memory store does not prove transaction order, locking, or partial failure, so do not use it to clear a data-migration change.
Skip the gate as your only review when the diff touches authentication, billing totals, or deletion. Those areas need explicit expected outcomes, not a snapshot of whatever the old code already did. Do not plan a team rollout around an unverified free quota or an assumed server lifetime from an old post. If today's documentation does not confirm the access terms you need, treat the assistant as optional. Keep the harness on a machine you control rather than on a shared environment you have not reviewed.
The closing claim stays modest, and a reviewer can audit it from the fixture diff alone. A four-hundred-line cleanup becomes reviewable when one characterized seam moves and the fixture file stays still. Everything else can wait for a later commit that states the behavior it intends to change. That later commit should carry its own cases, rather than borrowing the freeze you used to keep this extraction honest.#testing #refactoring #python #programming #software #coding #development #engineering #inclusive #community
Require an Empty Fixture Diff Before Extracting a Batch Loop
Your Agent Renamed the Function — It Just Missed the Caller That Referenced It by String

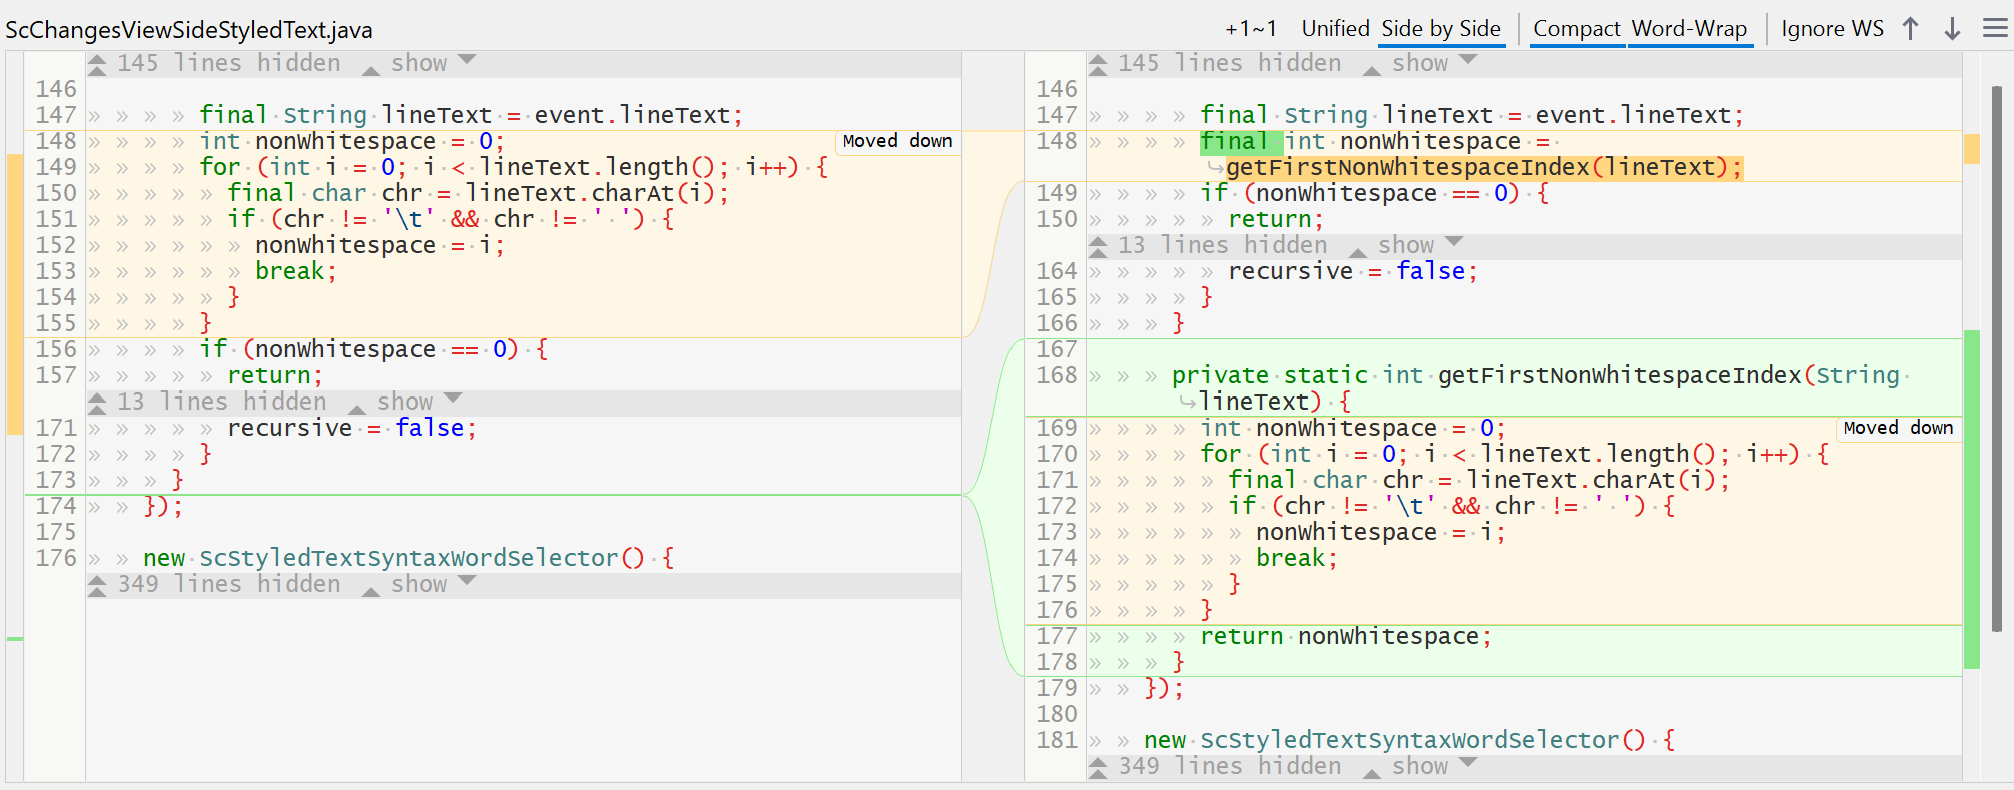
Moved a function into another file, and your diff shows it as deleted in one place and added in another?
SmartGit's Changes view now detects moved code, including moves across files. It links the old and the new location, so you review what changed instead of re-reading code that only moved.
It also finds moved fragments inside larger modified blocks, even if the code was reordered, split or partly edited. Move Detection is on by default and runs in the background, so the diff still appears right away.
Available in the SmartGit 26.2 Preview 👉 https://www.smartgit.dev/whats-new/26_2/
How do you review refactoring-heavy diffs today?
#Git #CodeReview #Refactoring #SmartGit #DeveloperTools
Alt...
SmartGit 26.2: Changes View: Move Detection

Agents Refactor 300K Lines in Three Weeks, and Practitioners Ask What It Proves
CodeScene has published a case study in which coding agents refactored a 300,000-line C codebase over three weeks,…
#NewsBeep #News #Artsanddesign #agenticrefactoringcasestudy #AI #AIdevelopment #Architecture&Design #Arts #ArtsAndDesign #CodeQuality #Design #Development #Entertainment #ML&DataEngineering #Refactoring #softwareengineering #TechnicalDebt #UK #UnitedKingdom
https://www.newsbeep.com/uk/787296/
BOOTOSHI 👑 (@KingBootoshi)
에이전트 기반 코드 생성에서는 초기 구현의 완성도보다 먼저 동작하는 기능을 빠르게 만든 뒤 리팩터링하는 2단계 워크플로가 고품질 코드로 이어진다는 주장이다. 모델이나 복잡한 워크플로보다 실행 가능한 초안을 우선 확보하는 방식에 초점을 둔다.
Nous Research (@NousResearch)
Nous Research는 Hermes Agent에 100만 줄 규모의 Python 코드베이스 정리를 맡긴 결과, 1,393개 서브에이전트가 19시간 동안 작업해 코드 규모를 34.4% 줄였다고 공개했다. 대규모 멀티에이전트 기반 리팩터링의 운영 사례로, 약 200만 달러 상당의 엔지니어링 시간을 절감했다는 회사 측 추정도 포함됐다.
AI (@DeepLearn007)
Teknium이 AI 서브에이전트 1,393개를 19시간 운용해 코드베이스 크기를 34.4% 줄이고, 엔지니어링 작업 시간 약 200만 달러 상당을 절감했다고 공유했다. 대규모 병렬 에이전트 활용이 리팩터링·레거시 코드 정리 비용을 줄일 수 있음을 보여주는 사례다.